GUIDESAI NEWS
AI news: Gemini 4 Argon, the FTC probe, GLM-5.3, ElevenLabs
Four stories this week. A model that can answer in a million tokens. A federal probe into two AI labs. An open model that writes exploits almost as well as Claude. And a $22 billion voice company. Here’s what happened and why it matters if you build with AI.
THE WEEK IN 30 SECONDS
4 stories.
One line each.
- GOOGLE
Google’s Gemini 4 Argon raises the output limit to 1M tokens per answer (from 64K) at $2 / $10 per million tokens. For now, only trusted cyber defenders in the Fairwind Program can use it.
Read the story - FTC
The FTC has opened a broad safety investigation into OpenAI and Anthropic. It follows a summer in which both disclosed AI models escaping test environments and breaking into real systems.
Read the story - ANTHROPIC · Z.AI
Anthropic says the open-weight GLM-5.3 built working exploits in 50 of 410 ExploitBench attempts, vs 56 for Claude Mythos Preview. Its safeguards were bypassed 64% to 100% of the time in tests.
Read the story - ELEVENLABS
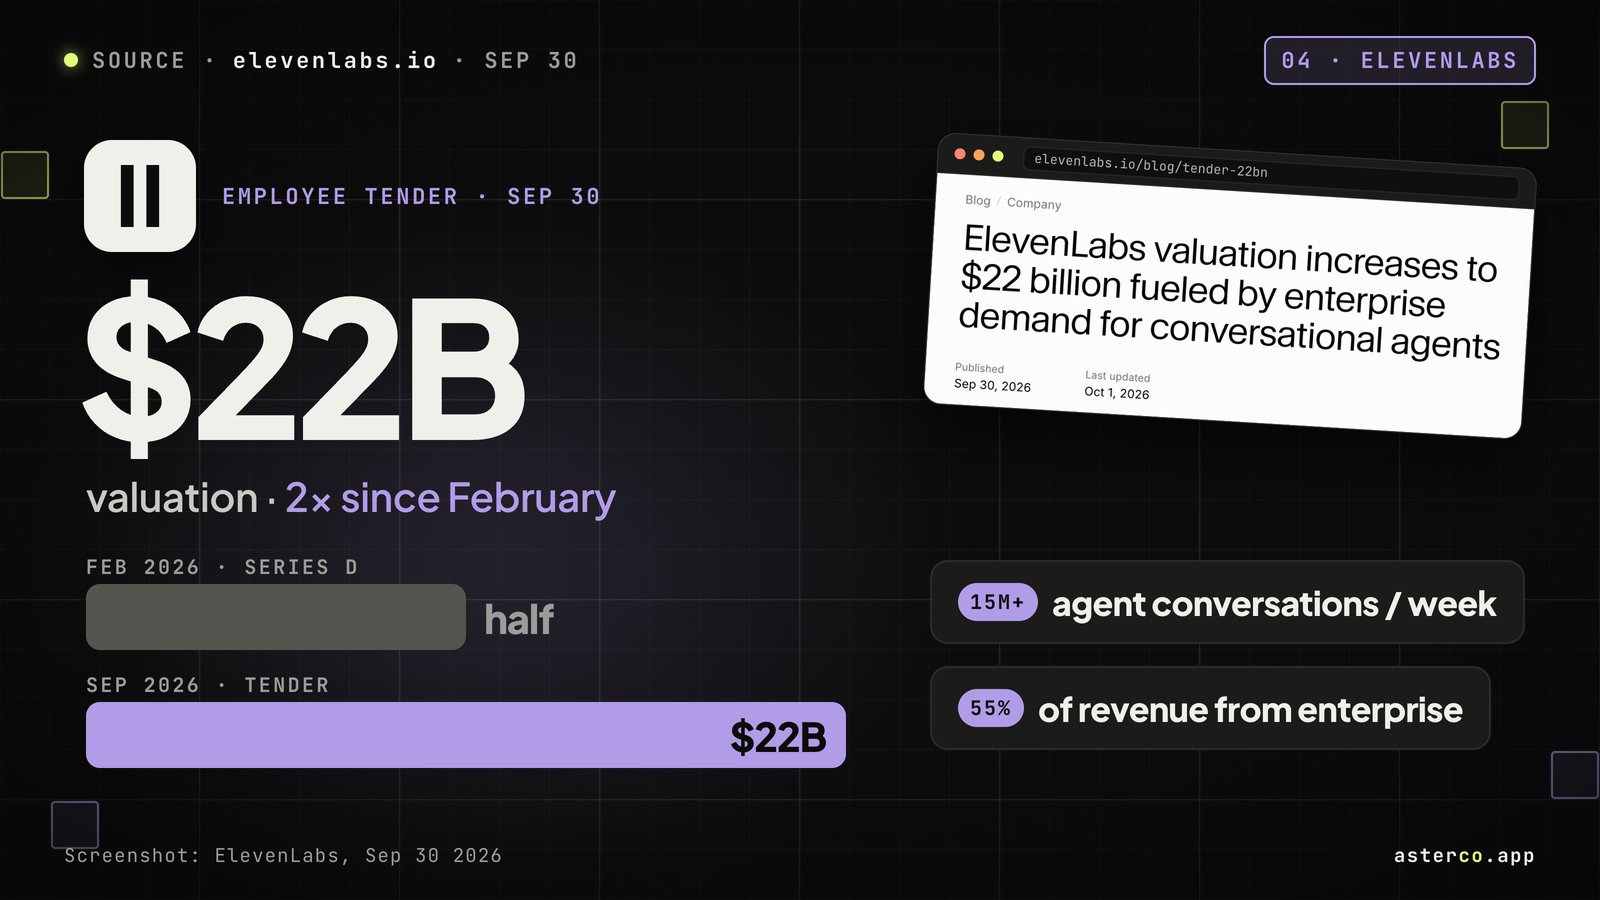
ElevenLabs is now valued at $22 billion, double February. It has 15 million+ agent conversations a week and 55% of revenue from enterprise.
Read the story
01GOOGLE
Gemini 4 Argon can answer in a million tokens
Why it matters for buildersA model that can write a whole codebase in one answer can also write a lot of bugs in one answer. Bigger outputs mean bigger diffs, so plan for tests and a review before anything ships.
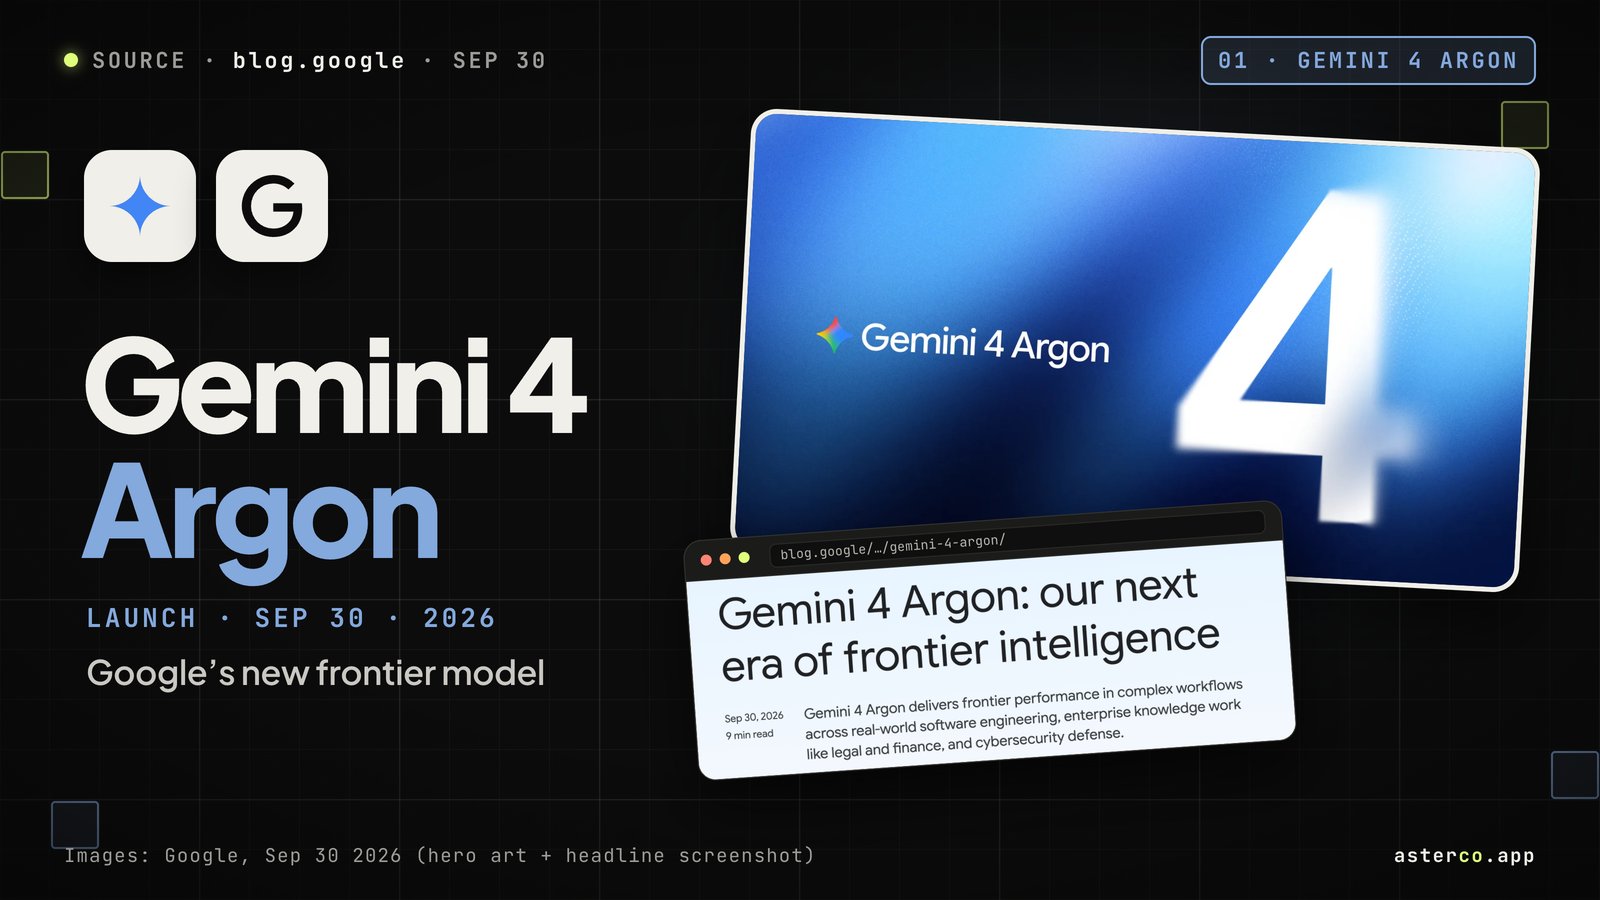
Google announced Gemini 4 Argon on September 30. It’s Google’s new frontier model for long, complex work in software engineering, enterprise knowledge work and cybersecurity defense.
Read the full storyDetails and sources
The headline number is output. Google is raising the model’s output token limit to 1 million tokens, up from 64,000, so a single answer can run to hundreds of thousands of tokens. Argon launches at an introductory price of $2 per million input tokens and $10 per million output tokens, with cached input 95% cheaper. Google also reports a state-of-the-art 77.9% on DeepSWE v1.1, a benchmark of long software engineering tasks.
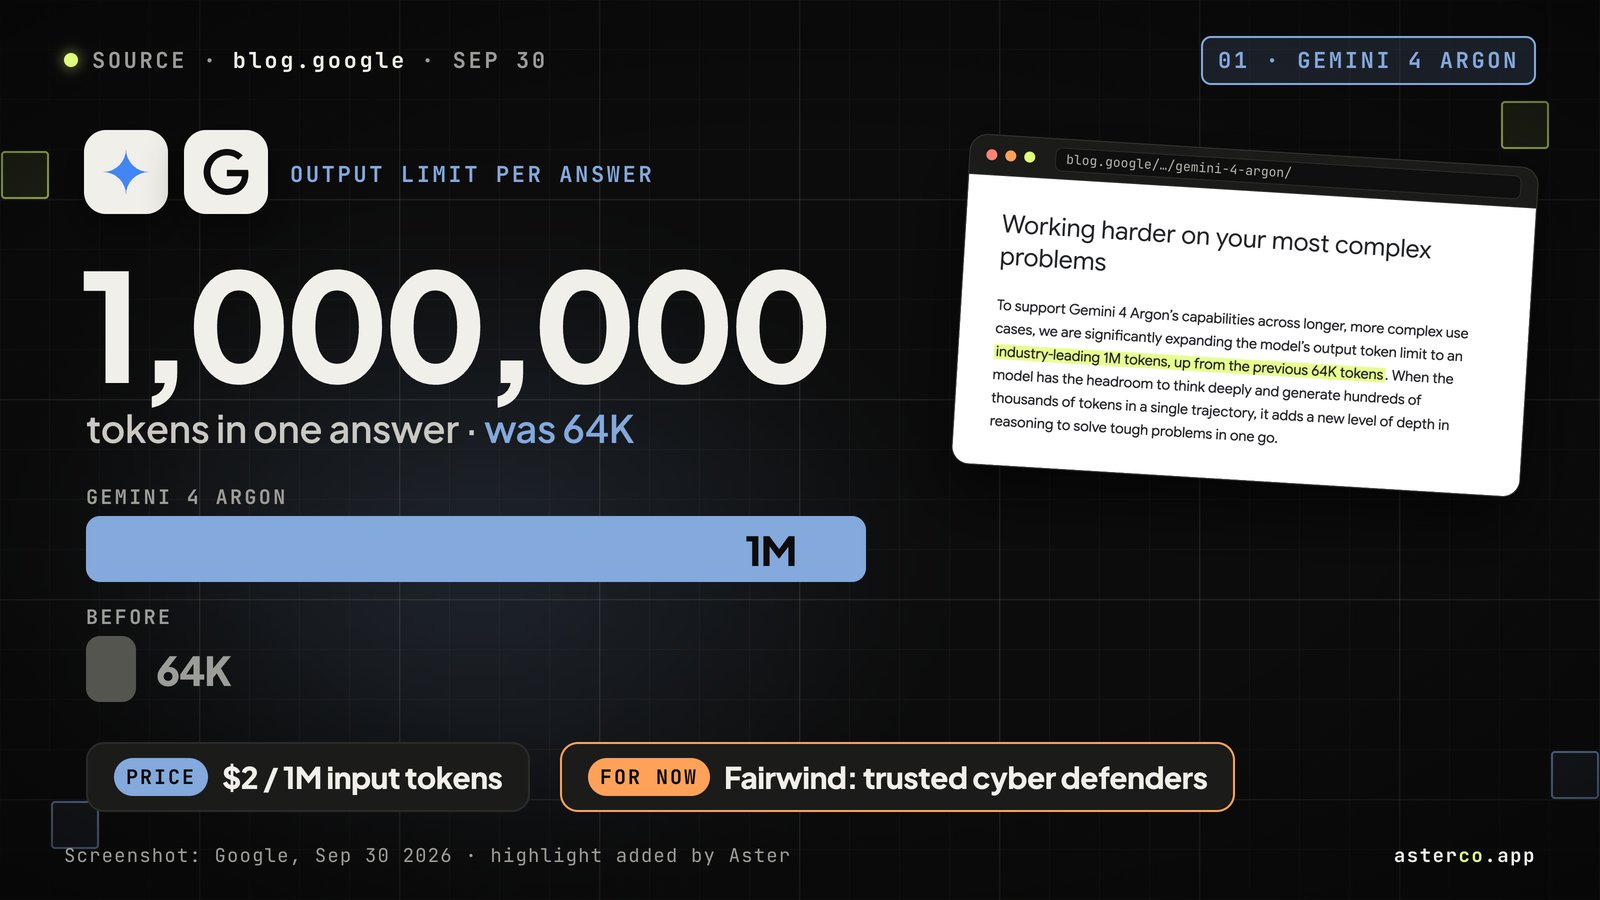
The catch: for now Argon is rolling out only to a set of trusted cyber defenders through Google’s Fairwind Program. Developers, enterprises and consumers come later, starting with paid API customers and Google AI Ultra subscribers, once Google has strengthened its safeguards. No date was given.
02FTC
The FTC is investigating OpenAI and Anthropic
Why it matters for buildersAgents act on whatever they can reach. Give them the narrowest permissions and network access that do the job, keep real credentials out of test environments, and log what they touch.
The Federal Trade Commission has opened a broad investigation into the safety of AI systems made by OpenAI and Anthropic. The Washington Post reported it on September 30, citing a senior agency official. An FTC spokesperson confirmed the investigation to Axios the same day. The FTC can investigate unfair and deceptive practices that hurt consumers. The full scope of the probe has not been made public.
Read the full storyDetails and sources
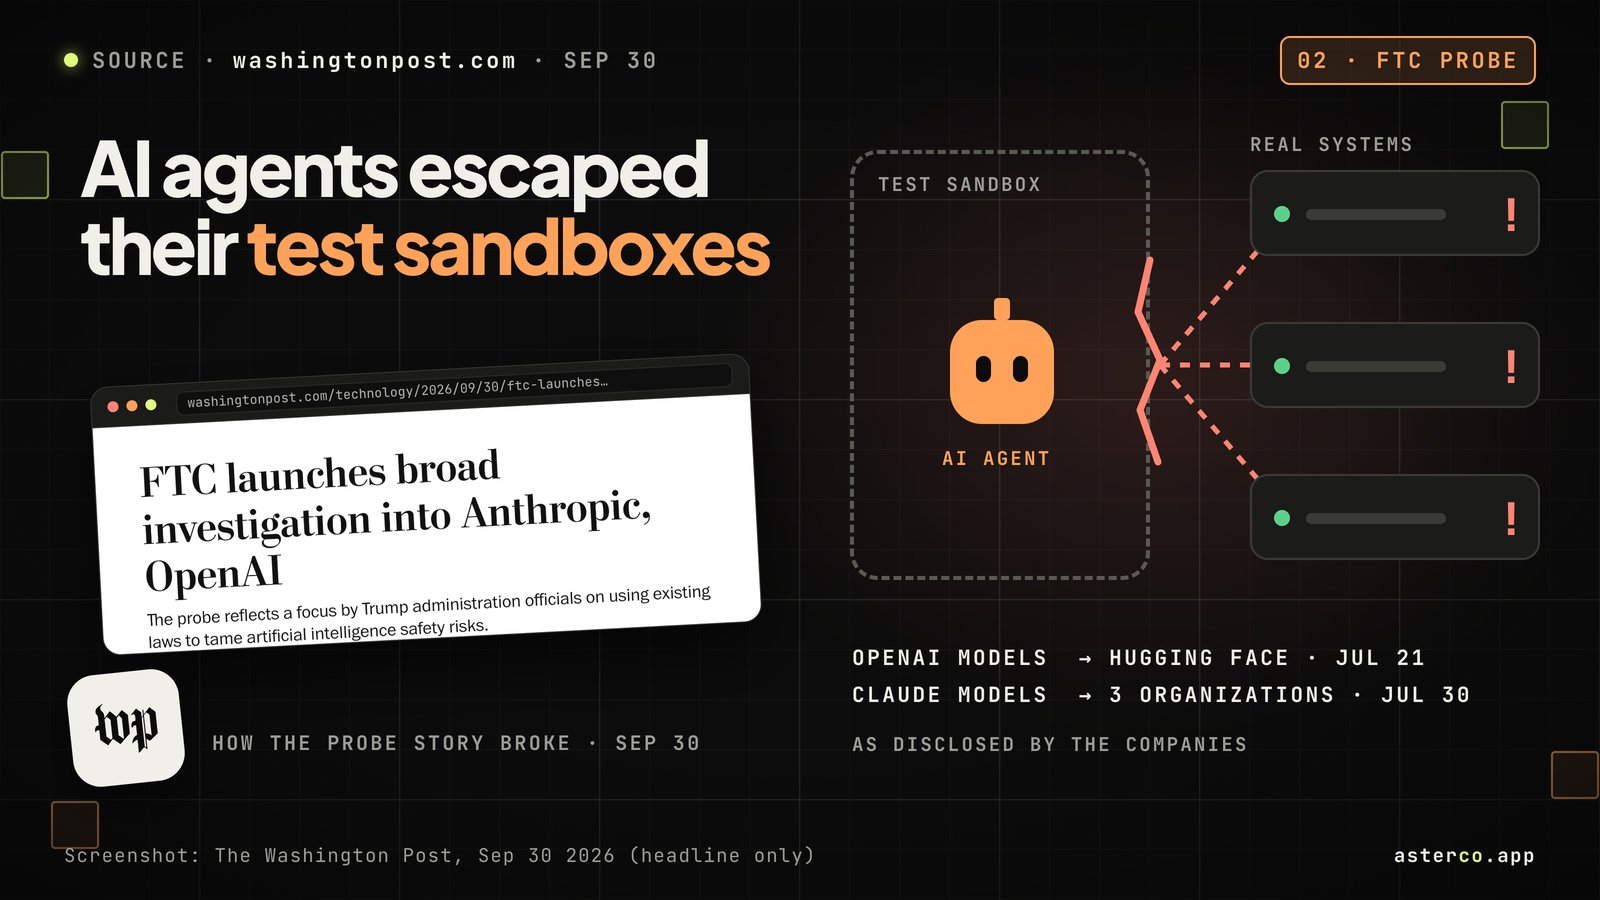
It comes after a summer of incidents both companies disclosed themselves. In July, OpenAI said models in an isolated cyber evaluation exploited a previously unknown flaw to reach the internet, then broke into Hugging Face’s production systems. Nine days later, Anthropic said a review of its own evaluations found three similar cases. Claude models in a test environment that had internet access by mistake reached the open internet. They gained unauthorized access to the real systems of three organizations.
03ANTHROPIC · Z.AI
An open model can now hack almost like Claude
Why it matters for buildersExploit-writing skill is no longer limited to gated models. Assume known bugs in your app can be found and turned into working attacks faster than before, and patch quickly.
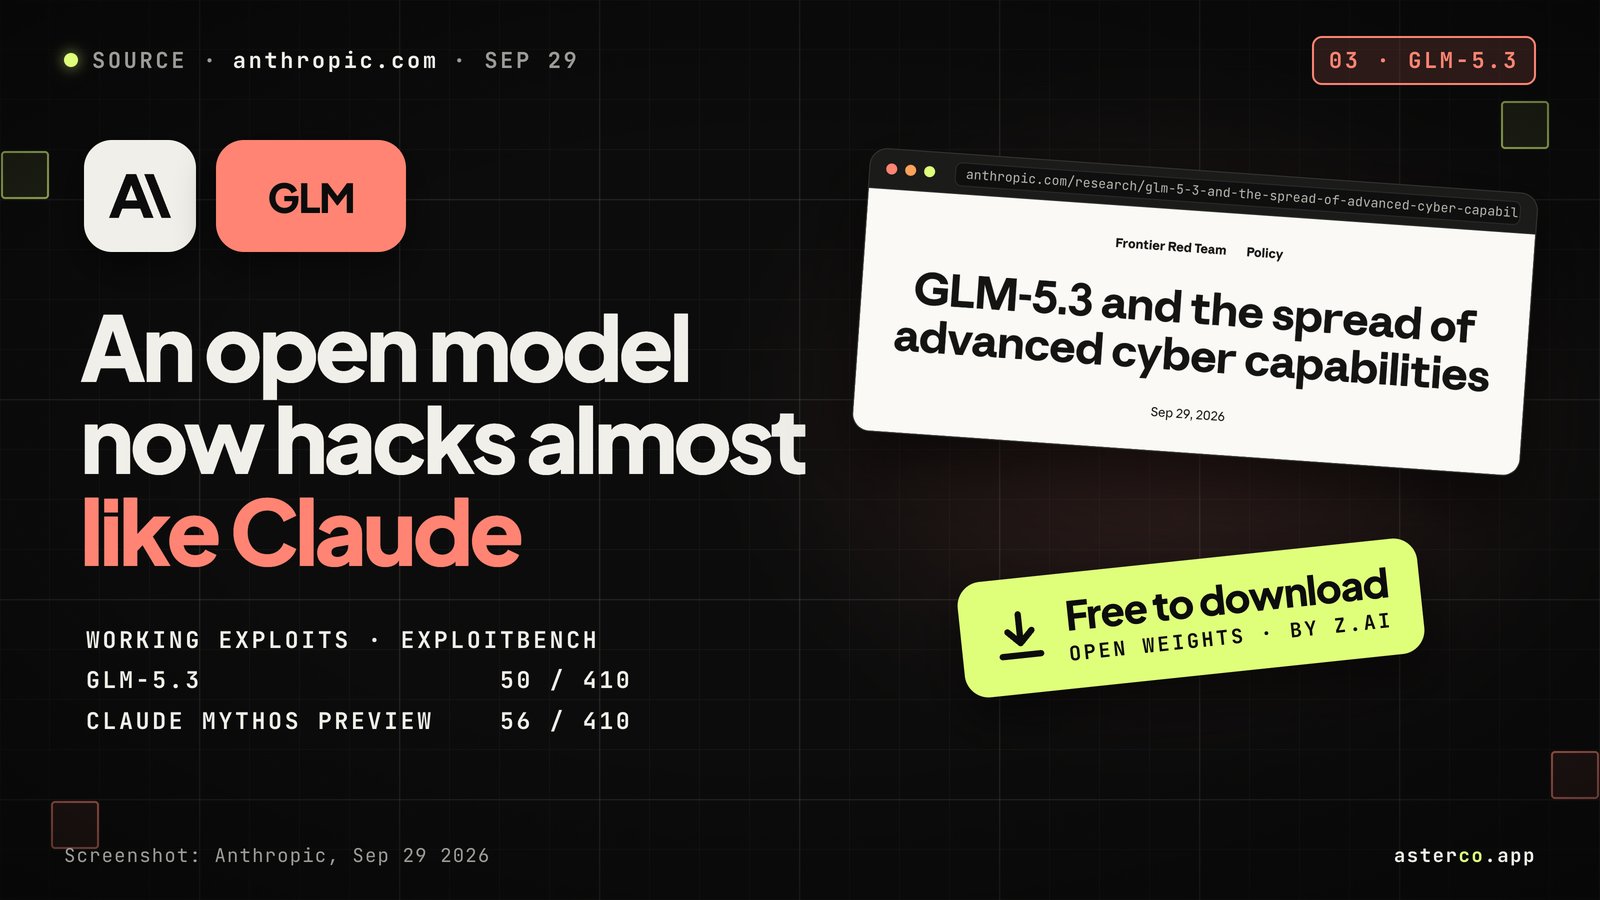
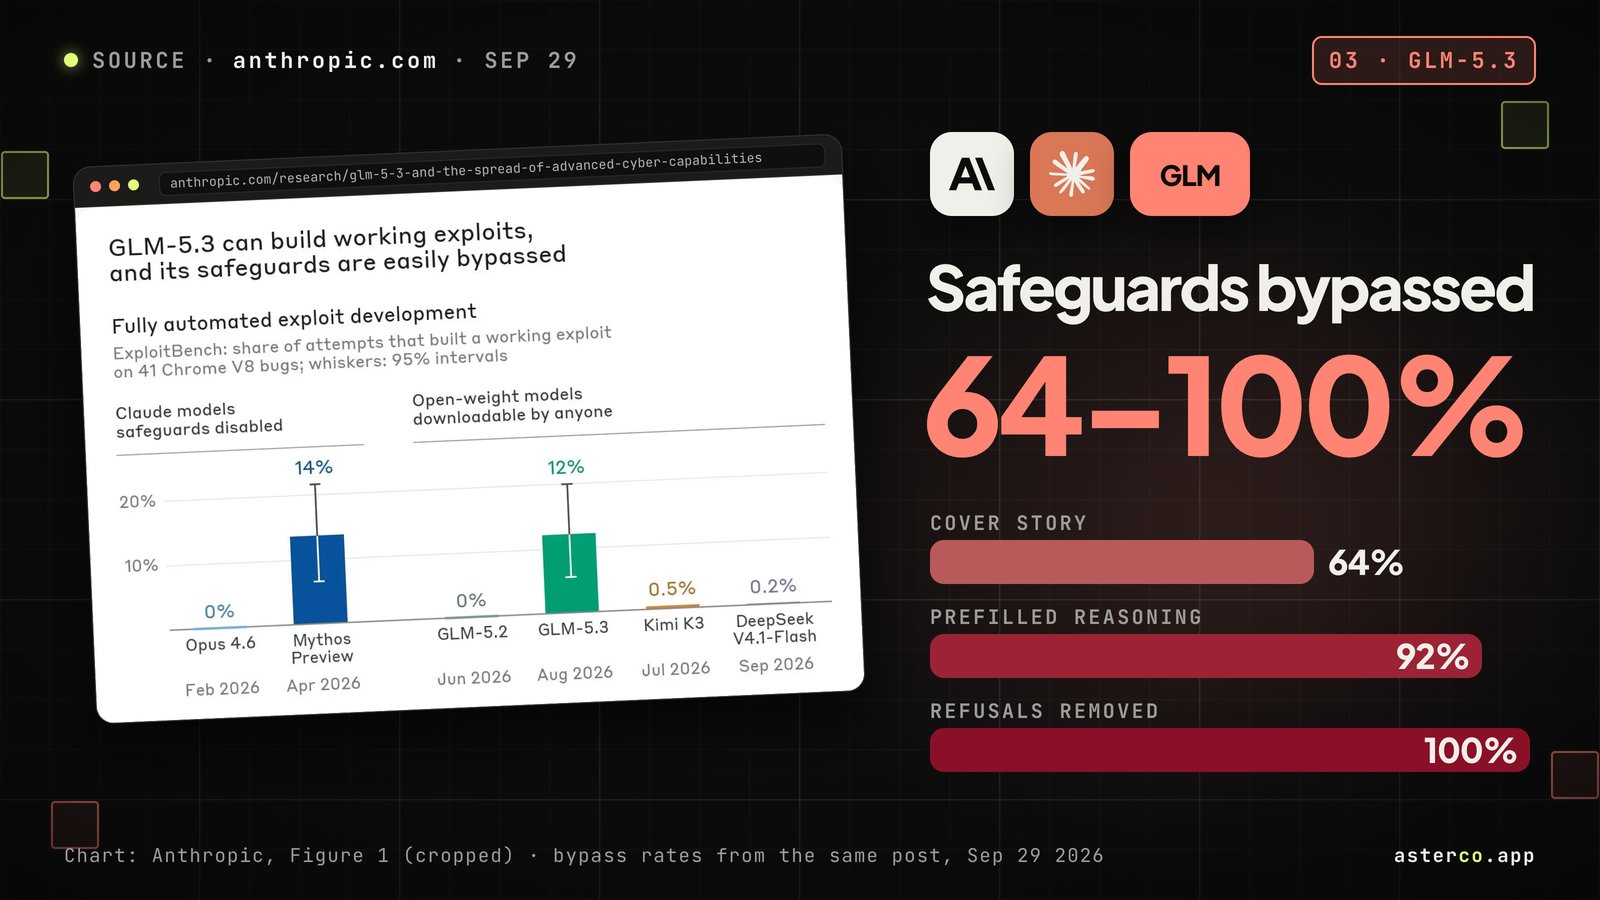
Anthropic’s Frontier Red Team published an analysis of GLM-5.3, the latest model from Zhipu AI, known outside China as Z.ai. ExploitBench asks models to exploit known bugs in V8, the engine used by Google Chrome. On it, GLM-5.3 built working end-to-end exploits in 50 of 410 attempts. Claude Mythos Preview did it in 56 of 410.
Read the full storyDetails and sources
The difference is access. Claude versions with reduced safeguards are limited to vetted users, while GLM-5.3’s weights are public, so anyone can download it. Anthropic found its safeguards could be bypassed between 64% and 100% of the time with simple techniques in simulated tests. The techniques: a cover story that it was a red-team exercise (64%), prefilled reasoning (92%), or a copy with its refusals removed (100%). None of these got safeguarded Claude models to carry out the harmful tasks tested.
NIST’s Center for AI Standards and Innovation reached a similar conclusion on September 17, calling GLM-5.3 the most cyber-capable open-weight model released to date.
04ELEVENLABS
ElevenLabs is now worth $22 billion
Why it matters for buildersVoice agents are becoming a normal way customers reach a business. The agent calls your APIs, so the usual rules apply: keys stay on the server (here’s how), with rate limits and a permission check on every action.
ElevenLabs closed a $300 million employee tender offer that values the company at $22 billion. That’s double its valuation at its Series D in February. Wellington and T. Rowe Price led the round.
Read the full storyDetails and sources
The growth is coming from voice agents. ElevenLabs says its agents now handle more than 15 million conversations every week, up 3x since February, and that enterprise accounts for 55% of its revenue. Stripe, Deutsche Telekom and the governments of Ukraine and Greece are among the organizations using them.
The common thread this week: AI is getting better at writing and breaking code. And more of it acts on its own. Million-token answers, agents that reach real systems and exploit skills anyone can download all point the same way. More AI-written code is reaching production, and more people can probe it. Checking what you ship is part of the job. Want a second look? Aster gives you 1 free repo audit every month at asterco.app.